Author: Karen

  • How to build Reader’s Web

    At first glance, Reader’s Web may seem like something that would require new browser features and years of standardization work. But it doesn’t.

    We can start building Reader’s Web today without waiting for browser vendors to support its document formats. In this article, I’ll explain how.

    Sub-webs

    The Web is a collection of all web pages. Originally, it consisted only of HTML pages. Over time, other document types were added. For example, PDF documents. A PDF document behaves like a web page: it can be viewed in a browser, and it can contain clickable links. Another document that behaves similarly is a standalone SVG image.

    A collection of documents of a particular type can be called a sub-web. We can talk about a “PDF sub-web” or an “SVG sub-web,” although such terms are not particularly useful.

    More interesting are the sub-webs we can create on the Reader’s Web. I call them static sub-webs because documents on the Reader’s Web are static—that is, they don’t contain scripts. Currently, the Reader’s Web includes the following document types:

    • HDOC (an HTML-based document containing an article)
    • CDOC (SVG-based collage document)
    • CONDOC (a connections document that allows the main document to be loaded from another URL)
    • Static comments (a JSON feed of comments that can be used in HDOCs)

    In the future, other document types may be added—for example, timelines or walkable 3D scenes. You can turn almost any application into a web of documents.

    Since in this article we are exploring how to build a sub-web, we don’t need to look into every document type that currently exists or may be added in the future. So, in this article I will focus only on HDOCs, using them to illustrate how sub-webs can be constructed.

    Recipe for creating a static sub-web

    Anybody can create sub-webs. The question is: once you create a new document type, how do you get browsers to support it? It turns out that you don’t have to.

    There is a way to introduce a new document type and popularize it on the Web without browsers explicitly supporting it. If it becomes popular enough, browsers may eventually start supporting it directly. But that support is not strictly necessary for the document type to be useful.

    Let me explain how it can be done using HDOC as an example.

    Step 1. Define the document type

    Define the new document type as if you expect browsers to support it. Now you have the document, but browsers don’t know how to render it.

    Step 2. Create a client app

    Create a client application—preferably a browser extension. You could create your own browser, but it’s much easier to create an extension focused on supporting the new document type while letting the existing browser handle everything else. It’s also easier to convince people to install an extension than to switch to a new browser.

    Now people with the extension can view HDOCs. The problem is that they are a tiny minority of all browser users. Most people don’t have the extension installed, so when they open an HDOC they’ll only see its source code. What’s worse, website owners will be reluctant to publish such documents because they won’t be readable for most visitors.

    Step 3. Define an embedded version

    Define an additional, hybrid version of the document. I call it an Embedded HDOC because it is embedded in a normal HTML page.

    Of course, you don’t simply add an entire HDOC containing the same content to an existing HTML page. Instead, you annotate the content of the HTML page and store all the additional information in JSON format. This allows the same URL to serve both formats. People with the extension installed will see an HDOC. Everybody else will see the original HTML page.

    So, we no longer have pages that appear as raw source code to most people.

    That leaves only one problem. If you, as a website owner, use new features such as visible connections, they’ll be available only to people who have installed the extension. That means you’d have to tell your readers something like:

    “To see the visible connections on this page, you need to install this browser extension.”

    For many website owners, that may be a deal breaker.

    Step 4. Serve Reader UI from your server

    Instead of relying solely on the browser extension, websites can serve the Reader UI themselves. This way, everyone gets the full functionality without being asked to install additional software.

    Such a page should also contain an Embedded HDOC in case someone wants to use the extension or load the page as a connected document next to another document.

    In the end, all you need is a browser extension and some server-side code.

    For HDOCs, the extension can be downloaded here. As for the server-side code, I’ve developed a WordPress plugin that you can find here.

    Circumventing browser restrictions

    On the Reader’s Web, you can connect pages to other pages and display visible connections between specific parts of their content. That means the main page must be able to request the connected page.

    If the connected page is hosted on another website, you can’t request it directly because browsers block such cross-origin requests. There are a couple of ways to work around that restriction.

    With the browser extension, you route the request through a background script. The background script is exempt from the browser’s cross-origin restrictions. You do, however, need to take measures to prevent a malicious web page from hijacking the background script which I have already done in my extension.

    When the Reader UI is served from the server and the extension is not used, you can instead use a proxy endpoint to forward requests to other websites.

    In that case, you need to make sure that other people can’t use your endpoint as a tunnel to request arbitrary URLs. In my plugin, the frontend sends not only the target URL but also the URL of the current page. The server then checks whether the current page lists the target URL among its outgoing connections. Only if it does is the request forwarded to the other website.

    Is it safe?

    Circumventing browser restrictions may seem dangerous. After all, those restrictions exist for a reason.

    In this case, however, we can make it safe.

    Browsers restrict scripts from reading data from other websites because those scripts are written by unknown authors and cannot be trusted to make requests on your behalf or access information from other origins.

    An HDOC, however, contains no scripts. The code that renders it is trusted code. Today, that code is provided by the browser extension. In the future, it could be built directly into the browser itself.

    The safety of this approach therefore depends on how thoroughly the document content is sanitized before it is rendered. I have designed both the browser extension and the WordPress plugin with security in mind and have made them as safe as possible to the best of my knowledge. As with any software, if security issues are discovered, they can be addressed in future updates.

    Server plugin

    Some document types, such as HDOC and Embedded HDOC, can be created manually and published as files on any website. However, server plugins can make adopting these new document formats much easier.

    Currently, there is one such plugin for WordPress sites: Reader’s Web Publisher. It allows you to serve your existing pages as hybrid pages. If a visitor has the browser extension installed, those pages are automatically rendered as HDOCs. Otherwise, visitors see the original HTML pages.

    Alternatively, you can serve your pages with Reader UI. In that case, everyone gets the Reader’s Web experience, regardless of whether they have the browser extension installed.

    Everybody gets what they want

    This approach gives everyone exactly what they need.

    A reader only has to install the browser extension to get the full Reader’s Web experience, including the ability to configure the theme for all supported documents.

    A website owner who uses visible connections wants to be sure that everyone will see those connections, regardless of whether they have the browser extension installed. Serving the Reader UI from the server makes that possible.

    And if a website owner simply likes the main idea of the Reader’s Web and wants to delegate the choice of the website’s theme to the reader, they can enable an option in the Reader UI that displays an informational popup explaining the Reader’s Web. Readers who find the idea interesting can then install the extension.

    To readers who aren’t familiar with the Reader’s Web, it will simply look as though many unrelated websites happen to use the same theme. Until browsers start supporting the Reader’s Web natively, you have to use some theme on your website whether you like it or not.

    Who can create static sub-webs?

    Because browser support is not required, anybody can define new document types and use the above “recipe” to create static sub-webs.

    You can turn any app into a web of documents. Take for example this web app that shows historical events on an interactive timeline. Here is a video that shows the timeline in action.

    The timeline, with its navigation, can be moved to a browser extension and a server plugin. A couple of web page document types can be defined for folders and layers of historical events. Currently, that information comes from the website’s database, but it can come from documents published on many different websites.

    And you can do so with almost any app. You just need to find a use case where turning an app into a web of documents makes sense. We don’t need to be too cautious. You can think of it as throwing things at a wall to see what sticks. Some of those document formats may become popular enough that eventually browsers may start supporting them directly. But even if that never happens, it doesn’t necessarily mean that those particular document types have “failed.” You can have niche sub-webs that are useful for some people but are never directly supported by browsers.

    What about browser support?

    While we don’t require browser support for the new document formats, we actually do want browsers to start supporting them at some point in the future. It will simplify a lot of things.

    For example, website owners won’t need proxy endpoints to circumvent browser restrictions when downloading a connected document from another website. That will make requests much faster, and the owners of the websites you request connected pages from will see your information in their analytics instead of the proxy server’s.

    The browser extension won’t be needed anymore.

    Server-side code will be simplified because you won’t need to serve the Reader UI from the server anymore.

    In the future, “forced” versions of embedded documents will become obsolete as well.
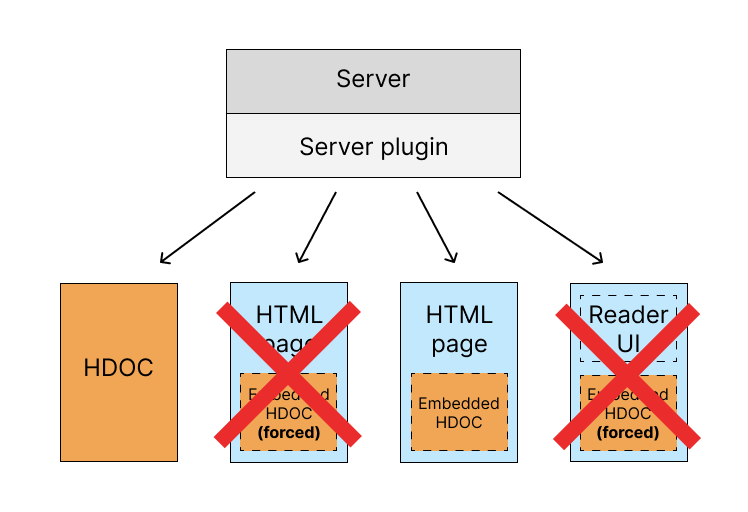
    In the future “forced” versions of embedded documents will become obsolete

    Around the time browsers start supporting Reader’s Web, content management systems like WordPress may start supporting it as well. At some point, you won’t need a server plugin or any special software at all. HDOC will become a first-class citizen of the Web.

    But for all of that to happen, we need all mainstream browsers to support Reader’s Web. Not some of them. Not most of them. All of them. If there is a noticeable percentage of people who can’t view standalone HDOCs because their browsers don’t support them, website owners will not start switching to standalone HDOCs and will continue using Embedded HDOCs and the Reader UI. And for any browser company that goes through the trouble of implementing support for Reader’s Web, it may seem that they have just wasted their resources on something pointless because nobody uses HDOC — the document format they have just started supporting.

    So achieving native browser support of Reader’s Web document formats is tricky. But the good news is that, as I said earlier, while we do want browsers to support Reader’s Web, we don’t need that support.

    If you focus on functionality, you will see that browser support won’t add any new functionality. If there is any functionality you think is missing from Reader’s Web, we can add it. Browser support will make things simpler, faster, and cleaner. But it won’t add any functionality that we can’t add ourselves.

    Problems we don’t need to worry about

    If you want to have a blog without having to worry about its design, or if you want to use visible connections between documents, it shouldn’t matter to you how popular or unpopular Reader’s Web currently is.

    The “network effect” is not important for the adoption of Reader’s Web document formats. It is important in other scenarios. For example, if you start a brand-new social media platform, you may fail to get enough users simply because people don’t want to join an empty social network.

    This is not the case with Reader’s Web. For a website owner, Reader’s Web is all about the new functionality it provides. And when you install all the required software, you get that functionality regardless of how many websites support Reader’s Web document formats.

    What we still need to work on

    Reader’s Web is by no means a finished project. Just as the World Wide Web has continued to evolve throughout its history, Reader’s Web will evolve as well. After revising the document formats several times, I believe they have now reached a stable foundation. Future changes should be additive rather than breaking existing documents.

    Here are a few areas I plan to work on as time permits.

    Coverage

    We have a WordPress plugin, but we don’t yet have plugins for other content management systems. That’s not a conceptual problem. It’s not that we don’t know what to do, and it doesn’t require permission from browser vendors. It’s simply a matter of doing the work.

    Once I see traction with the software we currently have, I plan to build similar tools for other platforms, not just WordPress.

    The same applies to the client software. At the moment, there is only a Chrome extension. In the future, I plan to develop versions for other browsers, starting with Safari.

    More styling options

    Currently, the extension provides three themes: light, dark, and sepia. Because the WordPress plugin uses the same Reader UI, website owners can also choose one of these themes for all pages on their site.

    The main idea behind Reader’s Web is that the reader, not the publisher, decides what a web page looks like. With only three themes available, it may look as though one developer is trying to decide what the entire Web should look like. That is definitely not the goal.

    Over time, I plan to add more themes or provide more granular control over fonts, colors, spacing, and other aspects of presentation. The goal is to give readers genuine freedom to choose how they want web pages to look, rather than limiting them to a handful of themes.

    Update (August 2026): There are now 11 color themes and 10 font sets, giving you 110 different styling options to choose from.

    Features for blogging

    HDOCs should eventually support most of the features available in a typical WordPress blog. For example, why not support categories?

    What if someone wants to build an entire website using HDOCs? Today, some pages—such as search results—still have to be regular HTML pages. Perhaps a dedicated static document format should be introduced for those pages. Maybe several formats. The goal is to allow an entire website to be presented consistently using Reader’s Web document formats.

    Richer connections

    Visible connections are currently one-to-one. They could be extended to support many-to-many relationships.

    Today, a connection ends with a dot on the collage side. Other endpoint types could be introduced. What if you want to connect to a rectangular region instead of a single point? Or attach annotations or small information popups? These are examples of features that could be added over time.

    Testing

    Reader’s Web is a fairly complex project. In many ways, it is like building a browser from scratch. You would therefore expect it to have a comprehensive test suite. At the moment, that is not the case. My priority has been implementing the core functionality, leaving less time for automated testing.

    As more people begin using the software, I expect bugs and edge cases to surface. My goal is to stabilize the project by adding comprehensive tests and creating a corpus of test documents that any Reader’s-Web-compatible client can use for compatibility testing.

    Future features

    Reader’s Web is inspired by Ted Nelson’s Project Xanadu. So far, I have focused on features that can be implemented on today’s Web, such as visible connections between documents. Over time, additional ideas inspired by Project Xanadu—such as stabilized content addresses, transclusions, and other capabilities—may be added as well. I made a video about it.

  • Forced Embedded HDOC

    There are now two kinds of Embedded HDOC: forced and non-forced.

    Forced Embedded HDOC

    If you open a forced Embedded HDOC with the browser extension installed, you will see it rendered as an HDOC. This allows website owners to “sit on the fence” by leaving the choice of document format to the user. Users who have the extension installed will see the HDOC version, while everyone else will see the original HTML page.

    Regular (non-forced) Embedded HDOC

    A regular (non-forced) Embedded HDOC can be used on pages where the website owner wants the page to always be presented as an HTML page with its custom styling preserved.

    Three types of web pages

    There are three general types of web pages:

    • a web app
    • a landing page
    • a blog post

    Let’s look at them one by one and see how Embedded HDOC can be used for each type.

    Web app

    A web app usually has dynamic content and interactive functionality. You generally don’t want to use visible connections on such pages. These pages are outside the scope of Reader’s Web, so we can ignore them.

    Landing page

    By “landing page,” I mean any page where the author:

    • want’s to use custom styles
    • doesn’t plan to use visible connections to other pages

    Such a page does not have to be a literal landing page. It can even be a blog post. What matters is that the author wants to preserve its custom styling.

    You should use a non-forced Embedded HDOC on such pages. It will always display the original HTML page with its custom styles unless the page is opened as a connected document.

    Blog post

    Blog posts can use the forced variant of Embedded HDOC. If you have the extension installed, such posts will always be rendered as HDOCs.

    Today, using my server plugin, you can serve four variants of HDOC.

    To better understand them you can read this article.

    In the future, once mainstream browsers support these document formats natively, forced Embedded HDOCs will be replaced by standalone HDOCs.

    Non-forced Embedded HDOCs, however, will not become obsolete even when browsers support standalone HDOCs. There will always be some pages where authors want to preserve their custom styling.

    Why would authors add Embedded HDOCs to their pages if they do not care about visible connections?

    In the future, when browsers support new document formats natively, content management systems like WordPress will likely support them as well. A server plugin will no longer be needed, and Embedded HDOCs may be added to landing pages automatically without website owners having to think about them.

  • List of Parsing Rules

    Below is a list of sites with their corresponding parsing rules. I’ll be updating this list over time.

    You’re welcome to create parsing rules for sites you use and share them in the comments. I’ll review them and add them to the list.

    If the comments attract too much spam, I may close them in the future and switch to another way of organizing collaboration around this list.

    en.wikipedia.org c/.mw-body-content/r/.navbox,.sidebar,.mw-editsection,.shortdescription,.navigation-not-searchable
    tim.blog c/.entry-content/r/.sharedaddy
    waitbutwhy.com c/.entry-content/t/article%20h1/r/%23social-ads/d/.date
    www.artofmanliness.com c/.post-content/d/%5Bitemprop%3D%22datePublished%22%5D/a/span%5Bitemprop%3D%22name%22%5D
    www.thehistoryblog.com c/.entry-content/t/.entry-title
  • CONDOC format description

    This specification on GitHub should be treated as the source of truth for CONDOC document format.

    1. Overview

    CONDOC stands for ‘connections document’. This document is used when you want to enhance other people’s content. A CONDOC does not contain primary content of its own. Instead, it specifies:

    • A reference to an external “main” document.
    • A set of outbound connections to additional documents. Connections may contain floating links.

    2. Structure

    A CONDOC document consists of the following top-level elements:

    <condoc> 
    <title>...</title> (optional) 
    <description>...</description> (optional) 
    <main>...</main> (required) 
    <connections>...</connections> (optional) 
    </condoc>

    2.1 <title> (optional)

    Human-readable title of the CONDOC.

    2.2 <description> (optional)

    A brief description of the purpose or scope of the CONDOC.

    2.3 <main> (required)

    A URL pointing to the primary document that this CONDOC enhances.
    The referenced document may be:

    • an HDOC (standalone or embedded in an HTML page),
    • a CDOC,
    • or a standard HTML document.
      When referencing HTML documents, parsing rules must be included in the URL.

    2.4 <connections> (optional)

    Container for all outgoing connections. The structure of this section is identical to the <connections> section defined for HDOC and CDOC documents.

    Example of CONDOC format:

    <condoc>

    <title>Famous Men of the Middle Ages</title>

    <description>The Project Gutenberg eBook with table of contents added as a separate document</description>

    <main>https://www.gutenberg.org/cache/epub/3725/pg3725-images.html#pr=c/body/r/.page</main>

    <connections>
    <doc url="https://readersweb.org/examples/famous-men/table-of-contents.hdoc" title="Table of contents of the Project Gutenberg eBook &quot;Famous Men of the Middle Ages&quot;" hash="1f25bd">
    i:25422;l:19;h:60e455;e:QUg=_i:5;l:19;h:3c1f60;e:QWg=
    i:33104;l:14;h:df0913;e:QU4=_i:43;l:14;h:457c77;e:QW4=
    ...
    </doc>
    </connections>

    </condoc>

    5. Example CONDOCs

    To view working examples, install the Visible Connections browser extension and open the following files:

  • Parsing rules

    Let’s say you want to connect your page to another page on a different website. There’s a problem: that other site doesn’t support HDOCs. Can we work around that? It turns out yes, we can. HDOCs are very simple. They’re basically a title and the content (plus a few optional fields). If you can locate those two things on a page, you can build an HDOC locally even if the original page isn’t an HDOC.

    In other words, we need to be able to parse arbitrary web pages. But all client apps must parse them the same way. If they don’t, you’ll end up in a situation where a floating link works in one app and looks broken in another. And you won’t be able to fix it, because the underlying text is slightly different depending on how each client parsed the page. We need deterministic parsing. That’s where parsing rules come in.

    Here’s what a URL with parsing rules may look like:

    https://example.com/some-page#pr=c/body/t/.main-title/r/.page,.some-class/d/.date/a/.author

    Everything after #pr= is the parsing rules section. It’s a set of key–value pairs where each value is a selector. Most of them are optional. The only required one is the content selector. Because of that, for many pages URLs with parsing rules will look much simpler, for example:

    https://example.com/some-page#pr=c/body

    Here are all the supported selectors:

    • c — content selector (required)
    • t — title selector (optional if the title is in an <h1> and is unambiguous)
    • r — list of selectors to remove from the final content (optional). Multiple selectors are separated by commas. Each selector is URL-encoded individually.
    • d — publication date selector (optional)
    • a — author name selector (optional)

    All selectors must be URL-encoded.

    Behind the scenes, a client app simply calls querySelector with the selector you provided. For the “remove” list, it calls querySelectorAll.

    How to find selectors using the RW Reader browser extension

    RW Reader has a parsing rules editor. I explain how to use it in this video.

    Good news

    Once you figure out the parsing rules, every client will parse the page identically. Users won’t even know parsing rules exist—everything “just works.”

    In the future we may create a public database of parsing rules for different websites which may be integrated with the extension, so you won’t have to come up with parsing rules that often, especially for the more popular websites.

    And over time—this is the optimistic scenario—HDOCs become common enough that parsing rules aren’t needed as often.

    Special case

    A special parsing rule exists for plain-text pages:

    https://example.com/some-page#pr=text

    Here "text" means the page is plain text and should be treated as such. Also, if the parser finds a line starting with Title: ..., it treats it as the page title in this case.

  • Embedded HDOC format description

    This specification on GitHub should be treated as the source of truth for Embedded HDOC document format.

    I originally designed HDOC as a standalone document format. In the future, when browsers and search engines support it natively, many HTML pages could be replaced with HDOCs. In most cases, the real content is stored in a database anyway, and changing the presentation layer is trivial. The problem is that right now, neither browsers nor search engines know anything about HDOCs. If you replace your HTML pages with HDOCs today, your site basically disappears for most people.

    One way around this is to serve HDOCs from separate endpoints. That lets you keep the original HTML page, but now you’re maintaining two URLs for essentially the same content. It would be much better if you could serve both the HTML page and the corresponding HDOC from a single URL. That’s exactly what the embedded HDOC format is for. It lets you embed an HDOC inside your HTML page.

    Which version a person sees depends on the software they use. Most visitors will just see the HTML page. Anyone with HDOC-aware software will see the HDOC version instead.

    To embed an HDOC into an HTML page, you need to do two things:

    1. Mark the element containing the page’s actual content with a special class called hdoc-content.
    2. Add a <script> tag with JSON content and the id hdoc-data that includes all the additional information needed to construct the HDOC locally.

    Example JSON:

    <script type="application/json" id="hdoc-data">
    {
    	"forced": true,
            "removal-selectors":".some-class,.other-class",
    	"panels":{...}
    	"header":{
    		"h1":"The title",
    		"author":"John Doe",
    		"date":"October 13, 2025"
    	},
    
    	"connections":[...]
    		
    	
    }
    </script>
    

    A client app will download the full HTML page, extract the content from the marked element, then read everything else from the JSON. With that information it can construct an HDOC—served from the exact same URL as the original HTML page.

    A panels section in the JSON may look like this:

     {
      "panels":{
          "top":{
             "site-name":"My website",
             "home-url":"https://example.com",
             "site-logo":"https://example.com/icon.png",
             "links":[
                {
                   "href":"https://example.com/archive",
                   "text":"Archive"
                }
             ]
          },
          "side":{
             "side":"left",
             "ipage":"https://example.com/interactive-page",
             "comments":{
                "url":"http://exmple.com/json-comments/?post=19",
                "title":"Comments",
                "empty":"No comments yet"
             }
          },
          "bottom":{
             "sections":[
                {
                   "title":"Section 1",
                   "links":[
                      {
                         "href":"https://example.com/about",
                         "text":"About us"
                      }
                   ]
                },
                {
                   "title":"Section 2",
                   "links":[
                      {
                         "href":"https://example.com/contacts",
                         "text":"Contacts"
                      }
                   ]
                }
             ],
             "bottom-message":"This is a bottom message"
          }
       }
    }
    

    A connections section may look like this:

    {
    "connections":[
       {
          "url":"https://example.com/dates",
          "title":"Dates",
          "hash":"d79712",
          "flinks":[
    "i:769;l:256;h:ff3d6e;e:Vy4=_i:0;l:8;h:e68ee0;e:RXM=",
    "i:1278;l:16;h:512358;e:THM=_i:35;l:11;h:1e5fac;e:Y3M="
    ]
       },
       {			   
          "url":"https://example.com/collage",
          "title":"Collage",
          "hash":"54dfa4",
          "flinks":[				 
    "i:2029;l:97;h:72bcf5;e:RS4=_p|x:79.772;y:142.467;r:0.147",
    "i:2423;l:79;h:7f7a20;e:Qi4=_p|x:81.226;y:142.1;r:0.147"
    ]
       }
      ]
    }
    

    The "removal-selectors" field is useful if some plugin has polluted your content with unnecessary elements. You can list selectors that HDOC-aware software should remove from the final content.

    "forced" field (optional): Boolean. When true, HDOC-aware clients should always render the page as an HDOC, including when it is opened directly as the main document. When absent or false, the client shows the original HTML page to direct visitors and uses the embedded HDOC only when the page is loaded as a connected document.

    You don’t need the metadata field if all you want is the page title. The client software will automatically use document.title from the HTML page.

    There may be other fields not described here. This format is still a draft, and I’ll make this and the other data formats more official in the near future.

    My WordPress plugin already supports embedded HDOCs. Once installed, it handles everything for you: marking the content, generating the JSON, and injecting it into the page. If you want, you can also define site-wide information in the plugin’s settings, and it will automatically include it in the JSON.

    The best part is that your site looks exactly the same as before to most people. You don’t need extra endpoints or duplicate pages just to make HDOCs available.

  • Examples of documents with visible connections

    This page was last updated on August 7, 2026.

    Here you’ll find a few examples of documents that use visible connections. Their purpose is simply to show the new capabilities now available to you. On their own, these examples aren’t particularly useful.

    In the near future, I’ll try to create materials that are useful, and I’ll also try to encourage others—mainly teachers and other educators—to create their own materials that make use of visible connections.

    To view these particular examples you’ll need to install RW Reader browser extension. Later I’ll add other examples that can be viewed without the extension.

    First example: a page connected to a page on another website

    Open this page.

    Second example: a page from another site connected to two other pages.

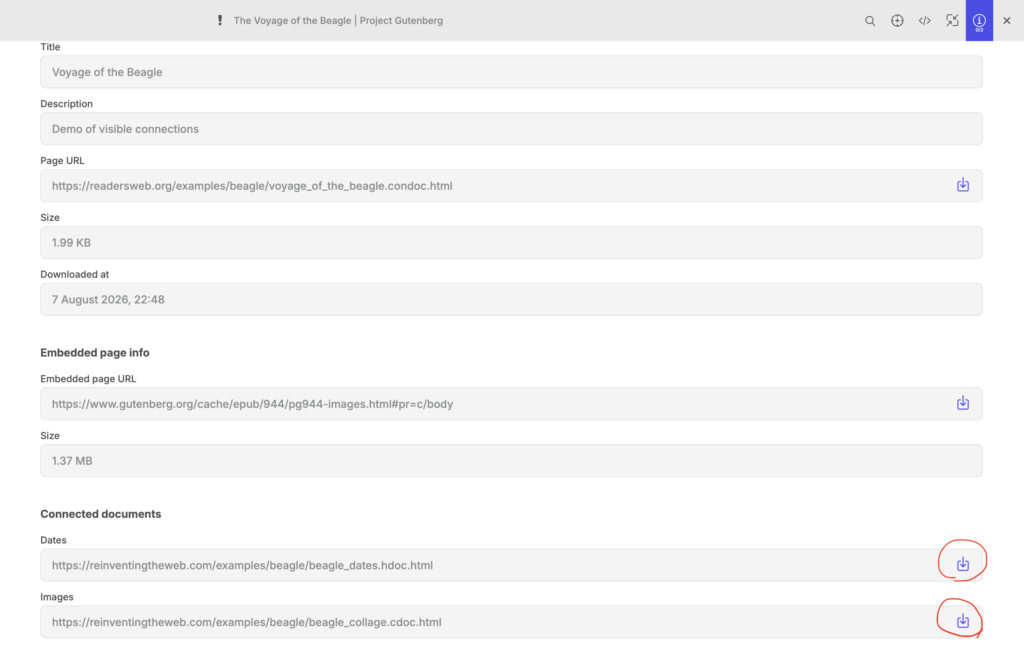
    Open this page. Click “download all connected documents” button that is located in the top right corner of the window. What’s interesting about this document, is that the main text (the book) is actually fetched from another site.

    Downloading examples in the LZ Desktop app.

    First, make sure that you have installed LZ Desktop and it’s currently running.

    Also install the extension LZ Desktop Helper.

    Now you can open the same examples in the browser and then download them into the app using the extension. Open extension’s popup and click “Download” button.

    In the app you download each connected document individually.

    You’ll have to put each document on the canvas.

  • Republishing on Reader’s Web

    Because pages on the Reader’s Web are self-sufficient and don’t require a live connection to the server to load some or all of their content, they can have a life of their own once downloaded. This will lead to a practice I call republishing. Imagine that anybody can take a page from your website and publish it on their website. Wait, what?!

    It may sound crazy at first, but let me explain.

    Why would people publish someone else’s content?

    Let’s say you want to publish a commentary on someone’s article. You can create an HDOC, write your commentary, then create a connection to the article in question and create floating links between the two pages. Then you publish HDOC on your website. When someone downloads it, they will see that your document references another document, download that document as well, and then they will be able to see visible connections (floating links) that you created.

    Here is an example of floating links between documents:

    The Problem: Content Instability

    All well and good, but what if the author of the article changes something in the article. It may break your floating links. There is a self healing mechanism that can fix broken links, but it doesn’t work in 100% of cases. Or, what if they completely delete their page? All your work writing commentary and adding links would go to waste. You need some way of stabilising the content of their article.

    In a centralised system like Ted Nelson’s Xanadu this problem is solved by simply saving every version of every document and never deleting anything. But in a decentralised system like the World Wide Web you don’t have a guarantee that a document on the other end of a link will not change or will even exist in the future.

    The Solution: Republishing

    The best way to ensure stability in a decentralized system is to host a copy of the article on your own site and connect your commentary to that copy rather than the original.

    Is this even legal?

    I believe republishing can become an accepted and expected practice, just like linking to webpages is today.

    By the way, linking wasn’t always a settled issue. In the early days of the Web some people seriously debated whether it was legal to link to someone else’s page without permission.

    Why would that be a problem? Imagine I have a popular website, and you run an obscure one. If you link to my site, your site becomes more useful, possibly gaining popularity. Do you now owe me something for benefiting from my content?

    Or what if I publish a private webpage meant only for friends? If you link to it from your popular website, you bring unwanted attention. Should you have asked first?

    Today, the consensus is that if you publish content on the Web, you should expect others to link to it. If you want privacy, use authentication. And maybe, you should even be thankful that somebody links to your content, because that brings you more traffic.

    Why should you be OK with republishing?

    The key is how republishing is done and what the republisher gains from it.

    When republishing someone’s page, you must not alter its content. In an HDOC, sections like <metadata>, <header>, <content>, <panels>, and <connections> remain intact. However, a <copy-info> section is added, containing the original page’s URL.

    Client software (browsers and storage apps like LZ Desktop) will clearly indicate that the page is a copy, displaying the original URL as its primary address. The page will look as though it was fetched from the original site, while making it obvious that it’s a copy. Users will be able to view detailed information and see its true source.

    Search Engines and Republishing

    Currently, search engines don’t index HDOCs, CDOCs, or SDOCs, but once they do, they’ll be able to distinguish between native content of a website and republished copies. That means republished pages won’t impact the search ranking of the host site.

    More importantly, republishers gain nothing from copying content other than stabilizing it for their floating links. Copying content is simply a technical detail of maintaining floating links, not theft. And just like with linking, you might even be grateful that others are preserving your content for free.

    Finding webpages that no longer exist

    Search engines could track every republished copy of an original webpage they find, ensuring that if that page disappears, users can still access reliable backups. However, this creates a risk: spammers might try to generate fake copies of recently vanished pages. To counter this, search engines may record multiple versions of each page, storing them as timestamped hashes. This way, when a page is lost, the search engine can analyze a network of its copies, identifying the most recent authentic version. If a spammer attempts to pass off a fake page, hash mismatches will expose the deception.

    A Backup System for the Web

    Republishing can serve as a redundancy mechanism, solving the problem of broken links.

    Random websites will help to preserve only some pages by republishing them.

    But in the future, there may exist services similar to the Web Archive that could store vast collections of static pages. These could be non-profits, commercial entities charging for access, or services that you pay to host backups of your content. Different business models could emerge.

    Such services could do more than passively store backups. Imagine your browser encountering a broken link. Instead of displaying a “404 Not Found” error, it could automatically request a copy from a backup service and seamlessly load the missing page. The page would be marked as a copy but still deliver the content the user was seeking.

    The Interplanetary Web

    Now, let’s take this a step further. Imagine a future where humans colonize Solar System. If we don’t do anything about our Web before that happens, there will be a separate Web on each planet, because of time delays in communication between planets.

    Many regular web pages are too dependent on live server connections. To have such pages available on Mars, for example, you’d have to have a copy of your entire web server there.

    Some popular websites like Wikipedia will probably be hosted this way on multiple planets. But most website owners won’t bother to host a copy of their websites on another planet.

    And so, the Web on Mars will be mostly separate and different from the Web on Earth.

    However, if we turn our Web into a web of static documents, time delays won’t be a problem. We’ll be able to use republishing mechanisms discussed above to have a copy of the entire Web in many places across the Solar System.

    Sure, some things that you have to run in containers, won’t work across large distances. For example, people from Earth and Mars won’t be able to play real time online games together. But that’s expected, and nothing can be done about it.

    The problem is that currently our entire Web is made of containers. And this needs to change. Bringing the Web to other planets is yet another reason to start the transformation of the Web.

    Republishing License

    I plan to publish a license or a declaration of principles to clarify the expectations around republishing.

    In my view, Reader’s Web is fundamentally about sharing. Readers should be able to download, cache, and even republish content by default.

    However, there is also an option to opt out on a case-by-case basis. This ensures flexibility for content creators who prefer to restrict republishing.

    Disclaimer

    Of course, none of this is legal advice. I’m not saying you can republish content today without consequences. If you think you could get in trouble for doing so, don’t do it. What I am saying is that republishing could one day become as normal as linking, helping to create a more stable, and scalable Web.

    This article was last updated on August 7, 2026.

  • CONNECTIONS format description

    This specification on GitHub should be treated as the source of truth for CONNECTIONS format.

    HDOC, CDOC and SDOC may all have <connections> section. It contains a list of documents the current document wants to connect to. Each connection may have a set of floating links.

    Child Element: <doc> (multiple)

    Contains information about a document.

    Attributes:

    • title (optional): Connected document’s title
    • url (required): Connected document’s url
    • hash (optional): SHA256 hash of the connected document’s content.
      • HDOC: Hash is calculated over textContent, not the HTML or innerText (to avoid whitespace modifications affecting highlight indices).
      • CDOC: Hash covers the entire <svg> section, including the <svg> tag.
      • Currently, the hash is generated upon export but is not verified when loading documents. This feature will be added later.

    Child Elements of <doc>

    A <doc> may contain floating links, which link:

    • Text segments in HDOCs
    • Points in collages (CDOCs)
    • Points in 3D scenes (SDOCs, not supported currently)

    Floating links are presented as lines with key value pairs. Examples:

    i:6771;l:22;h:abb7b7;e:MjE=_i:35;l:22
    i:7494;l:34;h:7ac799;e:TzI=_i:59;l:28;h:3fa088
    
    i:611629;l:149;h:f01591;e:VGw=_p|x:31.166;y:209.243;r:0.297
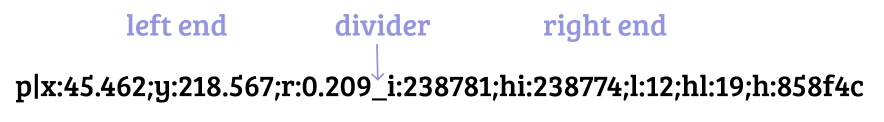
    i:238781;hi:238774;l:12;hl:19;h:858f4c;e:dmE=_p|x:45.462;y:218.567;r:0.209

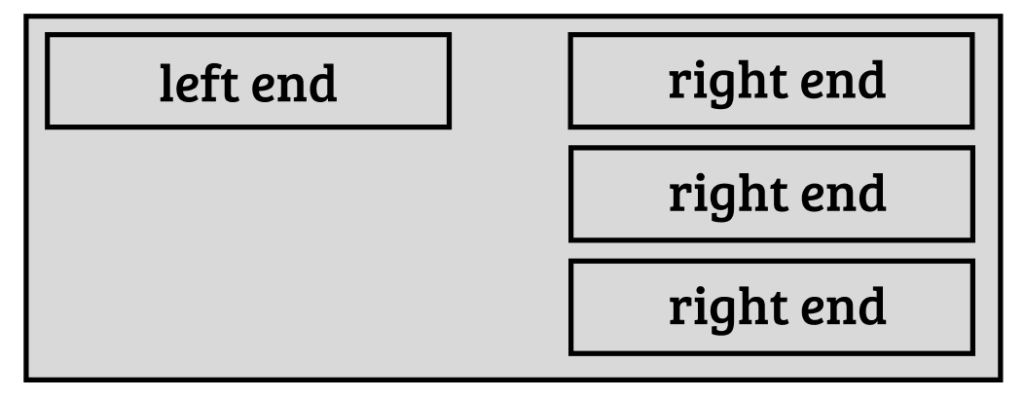
    A floating link has two ends:

    What end you use, depends on the document. For text documents you use a text end, for collages – a point end. There may be different combinations.

    Point-to-point links, for visible connections between two collages, are currently not supported but may be supported in the future.

    Two parts of a floating link are divided by an underscore.

    Point end

    Example:

    p|x:45.462;y:218.567;r:0.209
    • p → Point end type
    • x, y → 2D coordinates in a collage
    • r → Radius of a visible marker

    Text end

    Example:

    t|i:47703;l:33;h:c85272;e:QTI=
    • t → Text end type (default, can be omitted)
    • i → Index of the first character of the highlighted text
    • l → Length of the highlighted text
    • hi → Index of hashed range
    • hl → Length of hashed range
    • h → SHA256 hash
    • e → Ends of hashed range (first and last letter of hashed range concatinated into one string and then base64 encoded)

    Most text ends will appear without the t prefix:

    i:47703;l:33;h:c85272;e:QTI=

    Hashes in text ends

    Hashes are used, so we could tell if the link is broken because the text of a document was changed. And if the link is broken, in many cases the hash can help fix it by moving it to another index. The client app can simply move a range of a known length across the text and check at each tested index if the hash of a text within that range matches the known hash.

    • Hashes are generated for text segments that are unique and at least 10 characters long (character limit is used by LZ Desktop app when creating floating links, but it is not a requirement that will be set as a Web standard that all client apps must follow).
    • If highlighted text is too short or non-unique, the hash is computed for a larger surrounding range.
    • Default behavior: The hashed range extends left unless near the start of the document, in which case it can grow right as well.

    When the highlighted text is both long enough and unique, the hashed range coincides with it, making hi and hl unnecessary:

    i:6771;l:22;h:abb7b7;e:MjE=

    For text-to-text links, if both ends have the same hash, the second hash can be omitted. If the hashed range ends are the same (regardless of whether the hashes are the same or not) the “e” in the second text end can be omitted as well:

    i:6771;l:22;h:abb7b7;e:MjE=_i:35;l:22

    Ends of hashed range are stored so that if the link is ever broken, it can be fixed in a reasonable time. If you only use hashes, you may have to test a large number of positions in text by calculating hash for each of them. If the web page is a size of a book, it can take, for example, 30 seconds or even a minute to fix all broken links.

    If you know the first and last letter of the hashed string, you don’t need to check all possible positions, but only the ones where the first and the last letter match those stored in “e”. Because of that, the links with “e” parts can be fixed almost instantly.

    How this format can be extended

    I have only implemented floating links for the simplest possible use cases. In the future a lot more options can be added.

    We may want to be able to have multiple ends for one floating link. For example, you may want to create one commentary that is connected to multiple places in another document.

    We may need to distinguish different types of links. So, a type field can be added to floating links.

    Types can be, for example, Reference Link, Commentary Link, Correction Link, and many others. Some links may not even be links between two documents, but simply annotations within one document.

    New floating link ends

    For CDOCs (2D collages) a lot more link ends can be added besides a simple point marker. For example, you may want to frame something with a rectangle. You may want to add texts as overlays. All such cases can be handled by introducing new floating link ends.

    A collage may contain texts, so maybe we should be able to have text ends that are used in collages.

    Also, it may be useful to be able to target specific images within a collage instead of using absolute coordinates. This way, if an image position was changed, the link will not be broken.

    In 3D scenes (SDOCs) a support for 3D point ends and possibly other types of ends may be added in the future.

    Proper Xanalinks

    As I mentioned in other posts, this project is inspired by Ted Nelson’s project Xanadu. In Xanadu, there was a completely different mechanism for stabilising content of documents, so that links are never broken. That mechanism can be used in the Web 1.1 as well. It probably won’t be widespread, but I think it should exist as an option.

    Documents that support that mechanism, will be simply HDOCs that have an <edl> section.

    A new floating link end will be introduced for Xanalinks. It will be more complex than a regular text end with a hash.

    Because it’s just one end, it can be combined with other types of ends. So, you’ll be able to connect a Xanadoc (HDOC with an EDL section) to a regular HDOC. Or to a collage, 3D scene, or another Xanadoc.

    If for whatever reason you don’t want to use stabilized content addresses from EDL you’ll be able to use a simple text end over a Xanadoc. But in this case you won’t be using all the features a Xanadoc can provide.

    An example of an HDOC with CONNECTIONS section:

    <hdoc>
    <content>
    Content of the document...
    </content>
    <connections>
    
       <doc url="https://example.com/dates" title="Dates" hash="d79712">
          i:6771;l:22;h:abb7b7;e:MjE=_i:35;l:22
          i:7494;l:34;h:7ac799;e:TzI=_i:59;l:28;h:3fa088
          i:47703;l:33;h:c85272;e:QTI=_i:116;l:27;h:8de52f
       </doc>
    
       <doc url="https://example.com/collage" title="Collage" hash="54dfa4">
    i:611629;l:149;h:f01591;e:VGw=_p|x:31.166;y:209.243;r:0.297
    i:238781;hi:238774;l:12;hl:19;h:858f4c;e:dmE=_p|x:45.462;y:218.567;r:0.209
       </doc>
    
    </connections>
    </hdoc>
  • SDOC format description

    SDOC is a format for 3D scenes on the web. Just like HDOC and CDOC it is a static format, meaning that it cannot include any scripts.

    SDOC is currently not defined, but it will be similar to CDOC in that the main content will probably be located in a section that will use some popular format for 3D scenes, just like CDOC uses a popular 2D vector graphics format (SVG).

    SDOC will probably have <metadata> section, <copy-info> section, and <connections> section just like HDOC, and CDOC.

    SDOCs may contain HDOCs, CDOCs and even other SDOCs. All those documents may be included by reference.

    What will 3D scenes be used for?

    One use case I can think of is having something like a site map. Only instead of links to different pages you could have a 3D scene where you can surround your reader with your content.

    In the video example, I move things around. This will be possible with local scenes that user creates. SDOCs downloaded from the web will probably be immutable.

    Also, in the demo the 3D scene looks basic. But since the SDOC format will be based on some popular 3D format, you should be able to create scenes of any complexity.